- Hengqin Cooperation Zone Shares Cross-Border E-Commerce Developments, Focusing on Macao-Hengqin Collaboration and International MarketsOct 24, 2026View details
- A Shenyang study highlights the development of the “cross-border e-commerce + industrial cluster” modelOct 24, 2026View details
- Three China Advertising Association GEO group standards take effect on October 23Oct 24, 2026View details
- Amazon Raises Fulfillment Fees Twice, Yet the Median Platform Fee Remains Around 40%Oct 22, 2026View details
- AliExpress and YouTube Partner to Expand Marketing Opportunities for Chinese Brands Going GlobalOct 22, 2026View details
- Publicis says AI marketing is developing at two speeds, with agentic AI helping win clientsOct 21, 2026View details
How to troubleshoot Google indexing that is not updating?
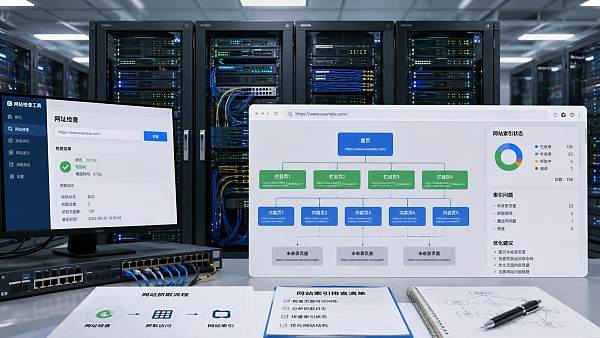
When Google indexing is not updated for a long time, do not focus only on the two statuses “Submitted” or “Crawled.” A page being discovered, crawlable, allowed to be indexed, and ultimately displayed consistently in search results are related but distinct stages. When troubleshooting, first confirm the status of the specific URL, then determine whether the issue lies with the page itself, site rules, or insufficient link and content signals.
The most effective starting point is to use the URL Inspection tool in Google Search Console. Enter the complete canonical URL rather than the homepage or a similar page. Pay close attention to whether the tool reports “Not indexed,” “Crawled - currently not indexed,” “Discovered - currently not indexed,” or “Alternate page with proper canonical tag.” These statuses may all appear to mean “not indexed,” but they require entirely different approaches.
First determine whether indexing has not been updated or the viewing method has caused a misjudgment
Many pages have actually been updated, but the search result title, snippet, or cached display may still retain old content. Search result snippets are dynamically extracted by the system based on query terms and are not guaranteed to use the page's latest meta description. If URL Inspection shows “URL is on Google” and the live test can retrieve the new page, indexing failure cannot be judged solely from the search result snippet.
URL version confusion should also be ruled out. Versions with or without www, http versus https, trailing slashes, case-sensitive paths, and links with tracking parameters may all be treated as different URLs. If the edited page is/product/, but internal links and the sitemap largely point to /product, canonical signals will be weakened and it will be easy to inspect the wrong version. Confirm that the canonical tag, redirect target, URLs in the XML Sitemap, and internal links all use the same standard URL.
When crawling is blocked, address accessibility and indexing directives first
The “Crawl” information in URL Inspection can help determine whether Googlebot can retrieve the page properly. If the server returns 401, 403, 429, 5xx, or times out, submitting an indexing request cannot bypass the issue. Temporary firewall rules, regional access restrictions, CAPTCHAs, human-verification plugins, and abnormal rate limits may allow regular browsers to open the page while preventing crawlers from accessing it consistently. Server access logs should be used to verify the response codes and response times for Googlebot requests, rather than checking only whether the frontend works properly.
- robots.txt blocks crawling: Check for
Disallowrules covering the target directory, especially rules left behind after a test directory has been moved to a production directory. - The page has noindex: Check the robots meta tag in the HTML and the
X-Robots-Tagin the HTTP response header. The latter is often overlooked and may be added globally through CDN, server configuration, or download file rules. - The canonical tag points to another page: If the canonical points to a category page, an old language page, or a page after parameter cleanup, Google may choose not to index the current URL. The canonical page itself must also be crawlable and indexable, and its content must genuinely be more suitable as the primary version.
- The page relies on scripts to load core content: If the title, main text, product attributes, or language-switching content is empty when rendering fails, the value of the crawled page will decline significantly. Use the live test in URL Inspection to view the rendered HTML and confirm that key text does not exist only in the page state after browser interaction.
“Crawled - currently not indexed” requires returning to an assessment of page value
This status indicates that access is usually not the main obstacle, but the search system has not yet considered the URL necessary to retain separately. The most common situation is duplicate or near-duplicate content: multilingual pages replace only a few words; product pages change only the model, color, or region; filter and sort pages generate many URLs with similar content; and paginated pages reuse the same title, description, and main text. Repeatedly submitting requests is unlikely to change the result in such cases.
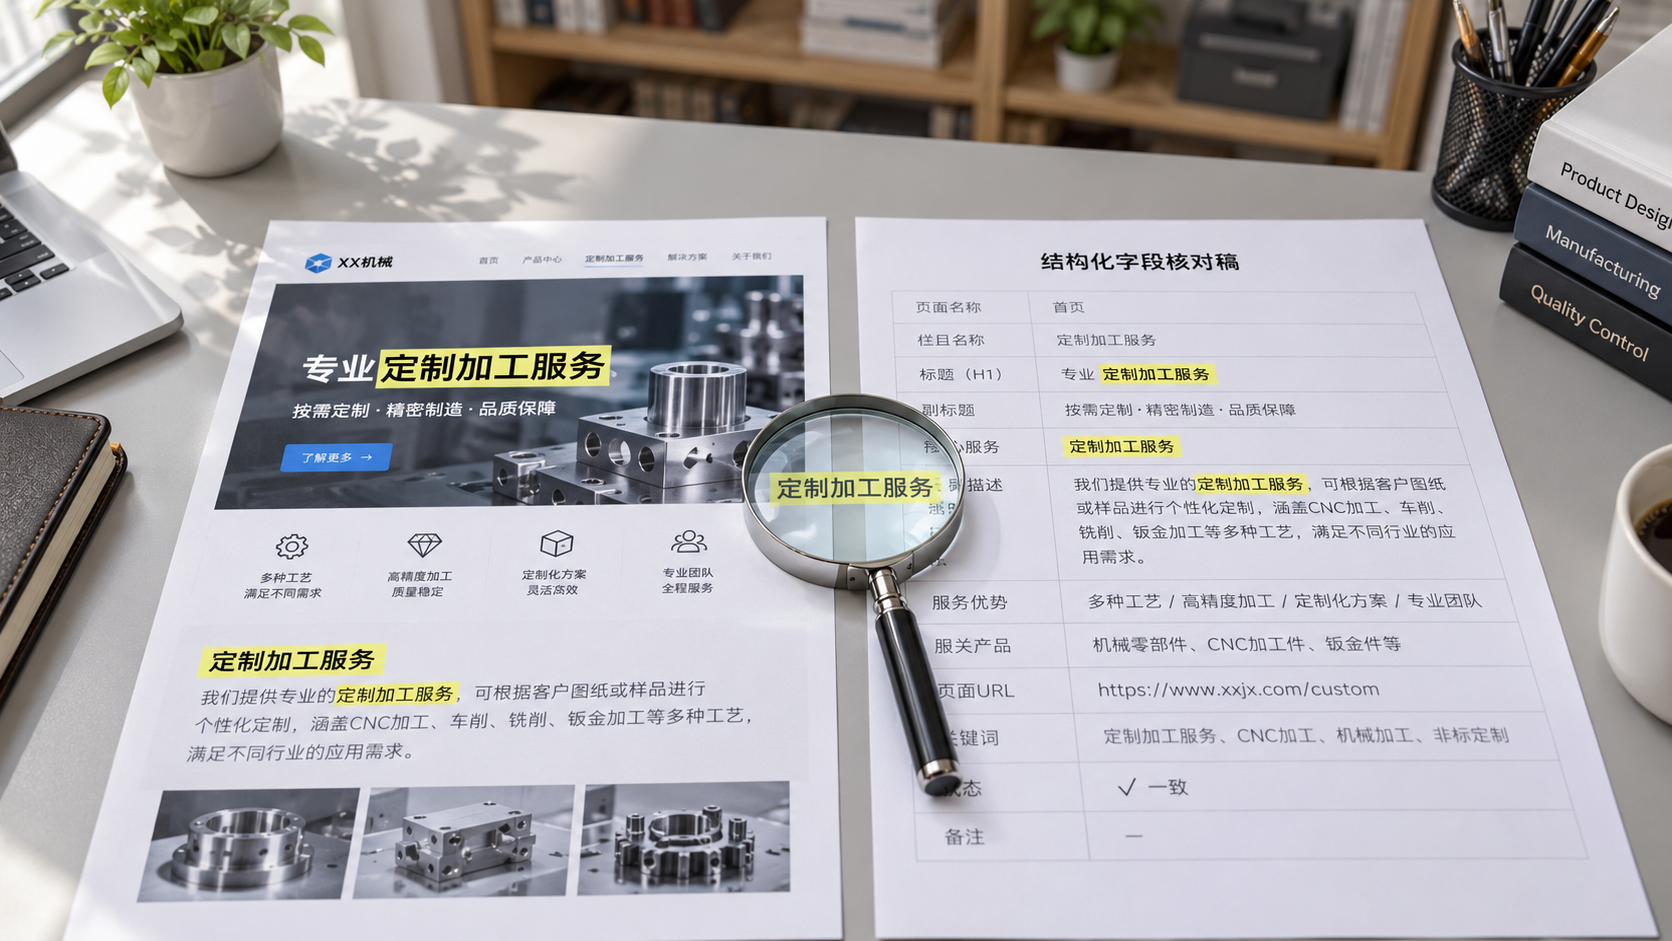
Compare the target page with the most similar pages on the site rather than reviewing only the copy on a single page. Check whether there are substantive differences in heading hierarchy, above-the-fold text, product specifications, application conditions, delivery information, FAQs, and image descriptions. For manufacturing or export product pages, differences in model, material, size range, operating conditions, and processing method should appear in readable body text; relying only on table images, PDF links, or gallery displays may not establish a clear page topic.
Thin content does not necessarily mean little text. A single-product page with clear parameters that supports ordering or inquiries can be short; however, if the page contains only a product name, generic promotional language, and repeated images, it is difficult for search systems to determine its independent value. Conversely, copying the same lengthy introduction across hundreds of pages will not increase the likelihood of indexing and may expand the scope of duplication.
Site structure determines whether new pages can receive sustained signals
Even if an orphan page is temporarily discovered through submission, it may not receive stable processing over time. The target page should at least be linked through standard HTML links from relevant category pages, product aggregation pages, or contextual recommendation links. Link anchor text should describe the page content, such as a specific product category or service topic, rather than repeatedly using “Click to view” or “Learn more.” Navigation can help pages be discovered, but topic-relevant contextual links better indicate the page's relationship within the site.
The purpose of an XML Sitemap is to provide a list of URLs to be discovered; it is not a guarantee of indexing. The sitemap should retain pages that return 200, allow indexing, and have canonical tags pointing to themselves; URLs that have already been redirected, return 404, have noindex, or are canonicalized to other URLs should be removed. If the sitemap submission time is constantly updated while many pages in it have conflicting statuses, it will increase troubleshooting noise and obscure the pages that genuinely require attention.
Check the relationships of multilingual and migrated pages
On multilingual sites,hreflang cannot replace canonical. Each language version should have its own indexable canonical URL, and links between language versions should return valid pages. Do not canonicalize all language pages to the Chinese or English main site, and do not allow different language versions to use almost identical machine-translated content. If a language version lacks localized body text, currency units, specification expressions, or business information, it can easily be regarded as highly duplicate.
After a website redesign, domain change, or URL structure adjustment, old pages should use a single-hop 301 redirect to the most closely matching new pages. Redirecting a large number of old product pages indiscriminately to the homepage weakens topical correspondence. Keeping both the new and old sites open, having canonical and redirect directions conflict, or continuing to submit old URLs in the sitemap will all slow the stabilization of indexing status.
Submit requests after fixes are made
Indexing requests are suitable for important newly created pages, substantive content updates, and verification after technical issues are fixed; they are not suitable as a bulk indexing tool. Before submission, first confirm that the page has been published to the correct environment, is not cached as an old version, returns a normal status code, and has consistent canonical tags and indexing directives. Then request indexing through the URL Inspection tool. Repeatedly requesting the same URL within a short period without any new page changes usually only wastes troubleshooting time.
After making fixes, keep a record of one inspection: the target URL, date discovered, page status, crawl time, changes made, and review result. This makes it possible to determine, if it still has not updated later, whether crawling has not yet occurred, the canonical page has been selected again, or the content remains too similar to other pages on the site. Only by identifying the status first and then applying the corresponding solution can the problem of Google indexing not updating for a long time avoid falling into repeated submissions and repeated guesswork.
Related Articles
 How Can an SEO Content Strategy Prevent Keyword Cannibalization?
 How can you check whether Schema markup matches the visible page content?
 Why Are Core Web Vitals Still Failing After Website Speed Optimization?
Related Products
 Yiyingbao SaaS Intelligent Website Building and Marketing SystemYiyingbao SaaS Intelligent Website Building and Marketing System, AI-powered no-code website building, rapid creation of multilingual B2B international websites in 10 minutes, global server acceleration, AI-powered SEO optimization, helping businesses connect efficiently with global markets. The perfect integration of technology and operation makes building an international trade website remarkably simple
 AI+SEM Intelligent Advertising Marketing SystemAI+SEM drives intelligent ad creation, empowering full-funnel precision advertising marketing. The system automatically generates weekly/monthly reports, AI recommends keywords and target countries, monitors core metrics in real-time with intelligent alerts, and enables one-click high-conversion ad solutions to help quickly acquire customers and improve ROI.
 AI+SEO Dual-Engine System Optimization ServicesYiyingbao’s AI+SEO dual-engine optimization system helps foreign trade enterprises acquire high-quality organic traffic through AI-powered keyword research, content generation, and comprehensive technical optimization, significantly improving search rankings and conversion rates.
 AI+SNS Social Media Marketing SystemYingbao AI+SNS Social Media Marketing System - Precision social capture for the social media era. Supports one-click content synchronization across major platforms like Facebook and LinkedIn. AI intelligently rewrites posts for enhanced relevance. 24/7 AI customer service and user profiling analysis empower businesses to efficiently expand into global markets.
 AI+SEO营销解决方案易营宝AI+SEO营销解决方案,通过AI批量写作、智能生成TDK、精准关键词扩词等功能,全面优化网站SEO效果,提升流量与转化率。助力企业构建高效智能网站新生态。
 AI+SEM Advertising Marketing SolutionsAI+SEM Advertising Marketing Solution leverages AI technology to deeply empower SEM ad campaigns. It automatically generates weekly/monthly reports using AI, presenting account data across multiple dimensions for comprehensive insights into campaign performance and trends. The system precisely recommends keywords and target countries, intelligently generates high-conversion ad copy, and enables one-click activation of efficient campaign plans to help businesses rapidly acquire customers. Simultaneously, it monitors core metrics in real time, intelligently identifies abnormal fluctuations, and issues timely alerts to ensure stable, high-return advertising results.
 Domain Name ServicesEasyWin provides professional domain name services, including intelligent queries, one-stop registration, brand protection, and full lifecycle management, helping businesses build a digital brand image.
 EasyOperate B2C Cross-Border E-Commerce Platform & Independent WebsiteEasyStore B2C Cross-border E-commerce Independent Store is an intelligent website building and cross-border e-commerce integrated solution independently developed by EasyStore Information Technology (Beijing) Co., Ltd. The system is specially designed for small and medium-sized as well as large export enterprises, integrating 'website building, operation, marketing, advertising, and conversion' into one, helping enterprises quickly establish cross-border e-commerce independent stores to achieve brand globalization and global sales growth.
The platform supports multiple languages, multiple currencies, and multi-channel marketing, with built-in AI intelligent translation and SEO optimization systems, suitable for mainstream markets such as Southeast Asia, Europe and America, Latin America, and the Middle East, assisting Chinese manufacturing enterprises in efficiently deploying international e-commerce strategies. SSL证书易营宝提供专业SSL安全证书服务,包括单域名和泛域名证书,确保网站数据传输加密、身份验证和完整性保护,助力企业建立安全可信的在线业务环境。