

- Which customer acquisition channels will be affected by cross-border marketing trends in 2026?Sep 06, 2026View details
- Which homogenization risks should be considered in an analysis of the AI-powered website building industry?Aug 30, 2026View details
- How Will AI Marketing Trends 2026 Change Advertising Budget AllocationAug 28, 2026View details
- Is the EV SSL certificate market shrinking or upgrading? How should companies assess certificate procurement?Aug 11, 2026View details
- Why the old AMP SEO 2020 practices no longer work and what has changed in current optimization prioritiesAug 02, 2026View details
- How to Choose Topics for an Industry News Section to Attract More Organic Search TrafficJul 29, 2026View details
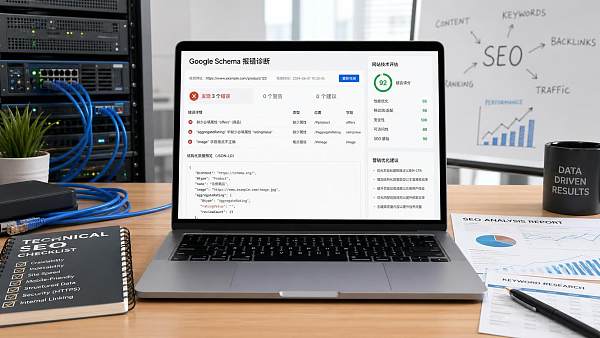
How to Troubleshoot Structured Data Errors with Google Schema Markup Validator
Check the error first; do not modify the code prematurely
When technical evaluators use google schema markup validator to troubleshoot structured data, the easiest mistake to make is not failing to understand the error, but changing fields immediately after seeing red text, which often makes the situation even more confusing. A more effective approach is to first determine which category the error belongs to: syntax error, type error, missing field, invalid field value, or inconsistency between the page content and the markup. The first two categories usually cause parsing failure, while the latter categories can often still be parsed but may affect how search engines understand the data and, in serious cases, cause rich results to become unavailable.
If you are responsible for website technical evaluation rather than day-to-day content maintenance, the assessment should focus on three questions: Does the error block parsing, does it affect the target page’s search appearance, and is it a template-level issue? These three factors determine the repair priority.
Where should you start when google schema markup validator reports an error?
First, check how the structured data is injected into the page. Many websites do not manually write JSON-LD; instead, it is dynamically generated by a CMS, theme template, plugin, tag management tool, or front-end component. Without identifying the source, it is difficult to locate the problem later.
During an actual investigation, I generally check the following in order:
- How many sections of structured data are actually present in the page source, and what type is each one?
- Which section does the error point to: JSON-LD, Microdata, or RDFa?
- Who generates this data—the template, plugin, or interface response?
- Do similar pages report the same error, indicating a single-page issue or a batch issue?
- Does the visible page content support these markups, avoiding a situation where the markup exists but the content is not displayed on the page?
This step may seem basic, but it is critical. In particular, when multilingual sites, product sites, and article sites share templates, the same code may produce completely different errors on different page types.
Which errors are most common, and how should they be prioritized?
Not all errors have the same severity. During a technical evaluation, it is advisable to examine them separately.
Many teams ignore warnings, but if a warning affects rich-result fields on which you rely, such as product price, inventory, or article publication date, it may not necessarily cause parsing failure but can directly affect how the page appears in search results.
Why does the validator report a syntax error even though the page opens normally?
Because browsers tolerate many front-end issues, while structured-data parsers do not. There are three typical situations.
- When the back-end template concatenates JSON, a field is empty and an extra comma is left at the end.
- The field value contains unescaped double quotation marks, breaking the entire JSON-LD section.
- Structured data is dynamically inserted with a script, but the output is object text rather than valid JSON.
Do not rely solely on visual inspection of the page for this type of issue. Directly check the application/ld+json content in the source code. If necessary, copy a single JSON section into the validation tool for separate testing; this can locate the problem more quickly than troubleshooting the entire page at once.
What is the essential difference between “missing field” and “invalid field”?
The difference is significant. A missing field means that the markup information is incomplete; an invalid field means that the field has been filled in, but the format is not recognized. The former is common when the template fails to output complete business data, while the latter is more often caused by an incorrect format, enumeration value, or data type.
A common example is a product page with a price where the schema writes the price as text such as “USD 199,” combining the currency and number. The validator may report the value as invalid. Similarly, if a date is written in a non-standard format, page users may understand it, but the parser may not.
Therefore, when fixing the issue, do not only add the field name; also verify whether the field value format meets the requirements of the corresponding type. During the technical evaluation stage, this step can directly reveal whether the data-source design is standardized.
What are the consequences of choosing the wrong structured data type?
Choosing the wrong type is more troublesome than missing a field. It is not simply a matter of leaving something blank; the semantics of the entire section are misdirected. For example, forcing a Product type onto a corporate website’s service page, or applying FAQ or Review to an ordinary information page. If the page itself does not support this content, the validator may partially pass, but search engines will not subsequently interpret it as expected.
The assessment method is practical: first determine the main purpose of the page, then select the type that most closely matches the page’s primary subject. Do not add every possible schema merely to obtain more search exposure. For technical evaluators, whether the type matches the page intent is more important than whether markup has been added at all.
Is it normal or conflicting for multiple schema sections to appear on the same page?
It is normal, provided that they describe different entities on the same page or that the relationships between the entities are clear. For example, an article page may contain Article, BreadcrumbList, and Organization at the same time, which is generally acceptable. The problem lies in duplication and inconsistency.
Common conflicts include:
- The same product page outputs one Product set through a plugin and another through the template.
- The names, prices, or links in the two data sections are inconsistent.
- The breadcrumb path does not match the actual page navigation.
Even if the validator does not mark every issue in red, this situation should still be addressed. For search engines, duplicate entities increase the cost of interpretation and, in serious cases, may cause important signals to cancel each other out.
Why are rich results still not displayed after validation passes?
This is where many people misunderstand google schema markup validator. It addresses whether the data can be parsed correctly, not whether it will definitely appear in search results. Passing validation only indicates that the structured data is basically valid.
If rich results do not appear, you should usually check several additional items:
- Has the page been crawled and indexed?
- Does the page content itself meet the relevant display conditions?
- Is the structured data consistent with the visible information on the page?
- Is the target type within the range of displays currently supported by the search engine?
In other words, the validator is the first checkpoint, not the final tool for determining whether a display will be obtained. During an evaluation, technical staff should ideally report “correct parsing” and “obtained display” separately.
How can you identify a template-level error, and why should it take priority over a single-page error?
Check whether the error consistently appears on URLs of the same type. For example, if all product detail pages lack brand, or the publication date format is incorrect on all blog detail pages, this is a typical template-level issue. Its risk does not lie in one page, but in the fact that it will continue to spread as new pages are created.
The approach is simple: sample pages from the same directory, using the same template, and in different language versions. If the error pattern is consistent, prioritize fixing it at the template or data-interface layer. For teams using intelligent website-building systems or a unified back end for multiple sites, this type of issue can often be corrected across an entire batch of pages with a single change, delivering the highest repair benefit.
Which fields deserve the most attention during an evaluation?
There is no need to examine every property in depth. Start with the fields most closely related to the value of the page. The priorities differ by page type:
- Product pages: name, image, price, currency, inventory, and link.
- Article pages: title, publication date, update date, author, and main image.
- Corporate pages: organization name, official website, logo, and contact information.
- Breadcrumbs: whether the hierarchical names and target links are genuine and accessible.
If these core fields are unstable, there is little value in adding long-tail properties later. Get the main structure right first, then consider enhancements.
How can you confirm that the problem has really been resolved after fixing it?
Do not rely only on a successful local test. A more reliable confirmation method is to conduct a three-step review at the code, page, and sample levels.
- Code level: Confirm that the generation logic has been updated in the correct template or interface, rather than temporarily changing a single page.
- Page level: Recrawl the source code of the live page and confirm that the output has changed.
- Sample level: Check a sample of similar pages to verify that the result is not an isolated case involving an occasional normal URL.
If you are conducting technical acceptance for a website-building or overseas marketing project, this step is especially important. Structured-data errors are often not impossible to fix; rather, one page has been fixed while other pages continue to report errors.
What standard should be used to determine whether structured data meets requirements?
A sufficient standard is: It can be parsed consistently, its type matches the page, its core fields are complete, its field-value formats are correct, and it corresponds to the visible content on the page. Once these five conditions are met, the investigation of errors reported by google schema markup validator can generally be considered properly completed.
During a technical evaluation, there is no need to fill in every recommended property. First eliminate the key issues affecting parsing, understanding, and display, then determine whether it is necessary to further expand the schema types. This better matches the pace of real projects and makes it easier to implement the repair results in templates and processes rather than leaving them as one-time manual troubleshooting work.
Related Articles
Related Products
 Yiyingbao SaaS Intelligent Website Building and Marketing SystemYiyingbao SaaS Intelligent Website Building and Marketing System, AI-powered no-code website building, rapid creation of multilingual B2B international websites in 10 minutes, global server acceleration, AI-powered SEO optimization, helping businesses connect efficiently with global markets. The perfect integration of technology and operation makes building an international trade website remarkably simple
 AI+SEM Intelligent Advertising Marketing SystemAI+SEM drives intelligent ad creation, empowering full-funnel precision advertising marketing. The system automatically generates weekly/monthly reports, AI recommends keywords and target countries, monitors core metrics in real-time with intelligent alerts, and enables one-click high-conversion ad solutions to help quickly acquire customers and improve ROI.
 AI+SEO Dual-Engine System Optimization ServicesYiyingbao’s AI+SEO dual-engine optimization system helps foreign trade enterprises acquire high-quality organic traffic through AI-powered keyword research, content generation, and comprehensive technical optimization, significantly improving search rankings and conversion rates.
 AI+SNS Social Media Marketing SystemYingbao AI+SNS Social Media Marketing System - Precision social capture for the social media era. Supports one-click content synchronization across major platforms like Facebook and LinkedIn. AI intelligently rewrites posts for enhanced relevance. 24/7 AI customer service and user profiling analysis empower businesses to efficiently expand into global markets.
 AI+SEO营销解决方案易营宝AI+SEO营销解决方案,通过AI批量写作、智能生成TDK、精准关键词扩词等功能,全面优化网站SEO效果,提升流量与转化率。助力企业构建高效智能网站新生态。
 AI+SEM Advertising Marketing SolutionsAI+SEM Advertising Marketing Solution leverages AI technology to deeply empower SEM ad campaigns. It automatically generates weekly/monthly reports using AI, presenting account data across multiple dimensions for comprehensive insights into campaign performance and trends. The system precisely recommends keywords and target countries, intelligently generates high-conversion ad copy, and enables one-click activation of efficient campaign plans to help businesses rapidly acquire customers. Simultaneously, it monitors core metrics in real time, intelligently identifies abnormal fluctuations, and issues timely alerts to ensure stable, high-return advertising results.
 Domain Name ServicesEasyWin provides professional domain name services, including intelligent queries, one-stop registration, brand protection, and full lifecycle management, helping businesses build a digital brand image.
 EasyOperate B2C Cross-Border E-Commerce Platform & Independent WebsiteEasyStore B2C Cross-border E-commerce Independent Store is an intelligent website building and cross-border e-commerce integrated solution independently developed by EasyStore Information Technology (Beijing) Co., Ltd. The system is specially designed for small and medium-sized as well as large export enterprises, integrating 'website building, operation, marketing, advertising, and conversion' into one, helping enterprises quickly establish cross-border e-commerce independent stores to achieve brand globalization and global sales growth.
The platform supports multiple languages, multiple currencies, and multi-channel marketing, with built-in AI intelligent translation and SEO optimization systems, suitable for mainstream markets such as Southeast Asia, Europe and America, Latin America, and the Middle East, assisting Chinese manufacturing enterprises in efficiently deploying international e-commerce strategies. SSL证书易营宝提供专业SSL安全证书服务,包括单域名和泛域名证书,确保网站数据传输加密、身份验证和完整性保护,助力企业建立安全可信的在线业务环境。