- CBP Finalizes Electronic Rail Export Manifest Rule, Effective October 26, 2026Oct 26, 2026View details
- Amazon’s 2026 peak season surcharge takes effect on October 25Oct 26, 2026View details
- AI Is Eating SaaS: Three Real-World Cases in One AfternoonOct 25, 2026View details
- Exiger CEO: The SaaS Apocalypse Is Real, but It Means Something DifferentOct 25, 2026View details
- Hengqin Cooperation Zone Shares Cross-Border E-Commerce Developments, Focusing on Macao-Hengqin Collaboration and International MarketsOct 24, 2026View details
- A Shenyang study highlights the development of the “cross-border e-commerce + industrial cluster” modelOct 24, 2026View details
How Can You Use Entity Detection Tools to Identify Semantic Gaps in Your Content?
The page already includes the target keywords, yet still does not answer what users really want to know. What may be missing is not keyword frequency, but key entities, attributes, and the relationships between them. Entity detection tools can help identify these omissions, but the “uncovered entities” in their output should be treated only as clues for review, not as a checklist of content that must be added.
The key to identifying semantic gaps is to confirm what information users need to complete their current search task, whether the page provides that information, and whether it establishes clear, credible connections between the pieces of information. Including a keyword does not mean the question has been fully answered; identifying more entities does not mean the content is of higher quality.
First, distinguish between “not detected” and “not clearly explained”
Entities can be distinct objects such as brands, products, materials, organizations, and locations. Some semantic analysis tools also extract technical terms, attributes, and topic phrases, but not all of these outputs are named entities in the strict sense. Tools with similar names may have different detection scopes.
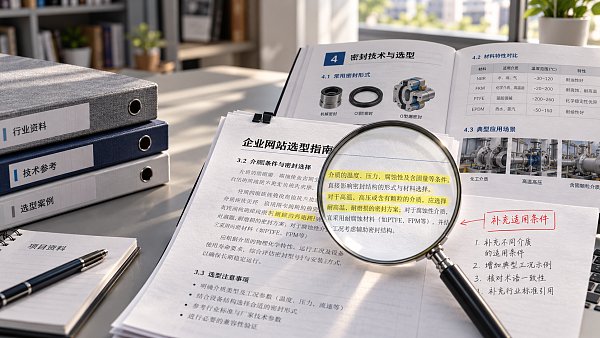
For example, a page about “stainless steel centrifugal pump selection” may mention “stainless steel,” “flow rate,” and “head,” yet still fail to explain how fluid temperature, viscosity, corrosiveness, and seal selection relate to one another. The gap here is not a lack of a few nouns, but a failure to explain how operating conditions affect pump selection.
Conversely, if a tool fails to identify a model number, that does not necessarily mean the page is missing information. Abbreviated model numbers, industry-specific terms, and translated names in different languages can all cause detection failures. Therefore, check the results against the original text; do not treat failed detection as proof that content is missing.
Make the page under review comparable to the reference content
Before running a check, write down a specific page task, such as “Help users select a centrifugal pump based on the fluid and operating conditions,” rather than a broad goal like “Introduce centrifugal pumps.” This statement determines which entities are worth considering and which information should be excluded.
Reference pages should be similar to the target page in search task, language, and target market. A product detail page should not be compared directly with an encyclopedia entry, nor should a purchasing and selection page simply copy a repair guide. Select a small number of relevant pages from search results, then cross-check them against sources such as technical manuals and specification documents. A high ranking means a page is worth analyzing; it does not prove that every item it contains is accurate or necessary.
When extracting the main text, exclude navigation, footers, recommended articles, sidebars, and repeated modules. Otherwise, a tool may count product names in the site-wide menu as part of the page topic, creating the illusion of “comprehensive coverage.” When crawling a URL, also confirm that the tool can read dynamically loaded content. If you cannot confirm this, import cleaned main text and retain the title and subheadings separately.
Turn entity lists into actionable gap records
When choosing a tool, check whether it supports the target language, source-text locations, entity classification, and result export. Basic entity recognition services are suitable for extracting objects, while semantic analysis tools with reference-page comparison features can help identify possible omissions. Neither can replace an assessment of search intent.
After checking the target page and reference pages with the same tool and settings, first consolidate synonymous expressions. For example, “stainless steel 316L” and “316L stainless steel” should not simply be counted as two separate gaps; however, different material grades should not be merged just to reduce the number of entries. For multilingual pages, verify terminology in the target language rather than simply translating a Chinese entity list and applying it as is.
For each candidate gap, recording “evidence in the source text—user question—action to take” is more useful than recording a coverage score:
Some tools provide scores for “prominence,” “relevance,” or “confidence.” These scores may indicate how prominent an entity is in the text, how closely it relates to the topic, or how confident the tool is in its identification. They are not interchangeable, and none is a search engine ranking score. The fact that a term appears repeatedly on reference pages is also not enough to prove that the target page must use it just as often.
Fill gaps in decision-making information, not in a list of nouns
Gaps worth addressing first are those involving information that affects users’ understanding, comparison, or actions. Returning to centrifugal pump selection, if a page lists materials and specifications but does not explain how fluid conditions affect material and seal selection, this gap should be prioritized. Brand history and an accessories catalog, which have little bearing on the page’s task, do not need to be added as a matter of course.
When adding content, establish relationships between “entity—attribute—condition—impact.” For example, do not simply add the word “viscosity”; explain that viscosity is one of the inputs for selection and that relevant performance assessments should be based on applicable performance data or selection calculations. Likewise, mentioning “stainless steel” alone should not imply that it is suitable for all corrosive fluids.
Place information where users need it: put parameter explanations in the specifications section, position application limitations next to the application description, and put comprehensive comparisons across products on a separate page with internal links. If every gap is stuffed into the main text, the page can become a disorganized collection of terms instead of focused selection content.
When reviewing the changes, check both “what was added” and “whether the page is more useful”
Running the check again after revisions can confirm whether omitted entities are now expressed and whether synonyms have been consolidated correctly. More importantly, however, conduct a manual review: Does the added paragraph answer a specific question? Are the relationships described accurately? Are they supported by technical documentation? Have unrelated tangents been introduced?
Before publishing, keep a record of the changes, stating what was added and the basis for it. After publishing, observe changes in search queries, clicks on related pages, and valid customer inquiries. Rankings and traffic are also affected by crawling, competition, links, and other factors, so short-term changes cannot all be attributed to adding entities.
The most valuable outcome of entity detection is not a scorecard with every box turned green, but a revision record that explains, item by item, “why there is a gap, where to address it, and what the evidence is.” Suggestions that cannot be tied to real user questions should not be a reason to expand the content, even if the tool flags them repeatedly.
Related Articles
 How Can an SEO Content Strategy Prevent Keyword Cannibalization?
 Website Rankings Stuck on Page Two? How to Find Opportunities for Improvement
 SEO traffic suddenly dropped. How can you identify the affected pages?
Related Products
 Yiyingbao SaaS Intelligent Website Building and Marketing SystemYiyingbao SaaS Intelligent Website Building and Marketing System, AI-powered no-code website building, rapid creation of multilingual B2B international websites in 10 minutes, global server acceleration, AI-powered SEO optimization, helping businesses connect efficiently with global markets. The perfect integration of technology and operation makes building an international trade website remarkably simple
 AI+SEM Intelligent Advertising Marketing SystemAI+SEM drives intelligent ad creation, empowering full-funnel precision advertising marketing. The system automatically generates weekly/monthly reports, AI recommends keywords and target countries, monitors core metrics in real-time with intelligent alerts, and enables one-click high-conversion ad solutions to help quickly acquire customers and improve ROI.
 AI+SEO Dual-Engine System Optimization ServicesYiyingbao’s AI+SEO dual-engine optimization system helps foreign trade enterprises acquire high-quality organic traffic through AI-powered keyword research, content generation, and comprehensive technical optimization, significantly improving search rankings and conversion rates.
 AI+SNS Social Media Marketing SystemYingbao AI+SNS Social Media Marketing System - Precision social capture for the social media era. Supports one-click content synchronization across major platforms like Facebook and LinkedIn. AI intelligently rewrites posts for enhanced relevance. 24/7 AI customer service and user profiling analysis empower businesses to efficiently expand into global markets.
 AI+SEO营销解决方案易营宝AI+SEO营销解决方案,通过AI批量写作、智能生成TDK、精准关键词扩词等功能,全面优化网站SEO效果,提升流量与转化率。助力企业构建高效智能网站新生态。
 AI+SEM Advertising Marketing SolutionsAI+SEM Advertising Marketing Solution leverages AI technology to deeply empower SEM ad campaigns. It automatically generates weekly/monthly reports using AI, presenting account data across multiple dimensions for comprehensive insights into campaign performance and trends. The system precisely recommends keywords and target countries, intelligently generates high-conversion ad copy, and enables one-click activation of efficient campaign plans to help businesses rapidly acquire customers. Simultaneously, it monitors core metrics in real time, intelligently identifies abnormal fluctuations, and issues timely alerts to ensure stable, high-return advertising results.
 Domain Name ServicesEasyWin provides professional domain name services, including intelligent queries, one-stop registration, brand protection, and full lifecycle management, helping businesses build a digital brand image.
 EasyOperate B2C Cross-Border E-Commerce Platform & Independent WebsiteEasyStore B2C Cross-border E-commerce Independent Store is an intelligent website building and cross-border e-commerce integrated solution independently developed by EasyStore Information Technology (Beijing) Co., Ltd. The system is specially designed for small and medium-sized as well as large export enterprises, integrating 'website building, operation, marketing, advertising, and conversion' into one, helping enterprises quickly establish cross-border e-commerce independent stores to achieve brand globalization and global sales growth.
The platform supports multiple languages, multiple currencies, and multi-channel marketing, with built-in AI intelligent translation and SEO optimization systems, suitable for mainstream markets such as Southeast Asia, Europe and America, Latin America, and the Middle East, assisting Chinese manufacturing enterprises in efficiently deploying international e-commerce strategies. SSL证书易营宝提供专业SSL安全证书服务,包括单域名和泛域名证书,确保网站数据传输加密、身份验证和完整性保护,助力企业建立安全可信的在线业务环境。