









- 21st Century Business Herald: AI and CTV Become Core Growth Engines for Digital Marketing in Overseas MarketsNov 18, 2026View details
- China Presents 25 Cooperation Outcomes in Areas Including Cross-Border E-Commerce During APECNov 18, 2026View details
- AI Products Drive Hong Kong Exports Up 64.9% in September, Fastest Growth in Over 40 YearsNov 17, 2026View details
- National Bureau of Statistics: Foreign trade grew rapidly in October, providing stable support for global tradeNov 17, 2026View details
- The U.S. has ended the $800 de minimis exemption for non-postal shipments; express courier packages must be formally declared.Nov 16, 2026View details
- ASEAN Signs Digital Economy Framework Agreement, Moving Toward Harmonized Cross-Border E-Commerce RulesNov 15, 2026View details
How Can an AI Marketing Engine Reduce Repetitive Operations in Cross-Border E-Commerce
Repetitive operations in cross-border e-commerce are often caused not by having too many tasks, but by repeatedly moving the same product information, the same set of selling points, and the same batch of campaign data across different channels. Creating a new language site requires reorganizing category pages, landing pages are not updated after ad creatives are revised, social media content continues to use old prices or specifications, and reports need to be exported from multiple backends and consolidated. The value of an AI marketing engine lies in connecting these fragmented activities around a unified data source and reusable rules, so that content production, page publishing, campaign testing, and performance reviews no longer involve separate duplication.
First, unify “reusable marketing assets”
The starting point for reducing duplication is not to generate copy in batches immediately, but to first determine which information should only need to be maintained once. Product names, models, specifications, materials, applicable scenarios, inventory status, logistics restrictions, after-sales service boundaries, and main image versions should all have clear master data sources. If the product information itself is disorganized, AI will only replicate errors to more pages and channels more quickly.
For example, when the same product is intended for a retail site and an inquiry site, the core specifications can be shared, but the page presentation cannot be exactly the same. Retail pages need more information on variants, prices, delivery, and reviews; inquiry pages should highlight minimum order conditions, customization scope, delivery lead times, and inquiry entry points. An AI marketing engine should identify “shared fields” and “channel-specific fields,” generating different page modules from the same product information rather than copying an entire page and then manually deleting and revising content.
Multilingual content should follow the same logic. Structured fields such as product dimensions, power ratings, and packaging quantities should not be freely rewritten by the model; brand tone, selling-point order, and application descriptions can be adapted according to the target language. High-risk fields such as units, models, material grades, and shipping restrictions should be set as locked content. This way, when packaging specifications are updated or a model is discontinued, only the source field needs to be changed, and the relevant sites, advertising landing pages, and content templates can enter a pending synchronization status.
Turn website building into modular assembly rather than page rebuilding
Repeated website building is common during market expansion: an existing English website already has a category structure, but after adding a new region or language, the navigation, product pages, forms, and content blocks are redesigned from scratch. Although the pages may appear different, their underlying components are often highly similar. Breaking headers, filters, specification tables, trust information, inquiry forms, related recommendations, and footers into configurable modules can significantly reduce subsequent maintenance workloads.
Here, an AI marketing engine should not only be responsible for writing headlines, but should also participate in page structure matching. Based on product type, conversion goals, and the existing module library, it can select suitable content frameworks for category pages, detail pages, or advertising pages. For example, for industrial products with complex specifications, priority should be given to specification tables, application illustrations, and download links for materials; for consumer goods with stronger visual decision-making, greater weight can be placed on scenario images, variant selection, and review sections. Reusable page modules do not mean that pages in every market should be identical; differences should be reflected in language, currency, delivery rules, featured categories, and conversion entry points.
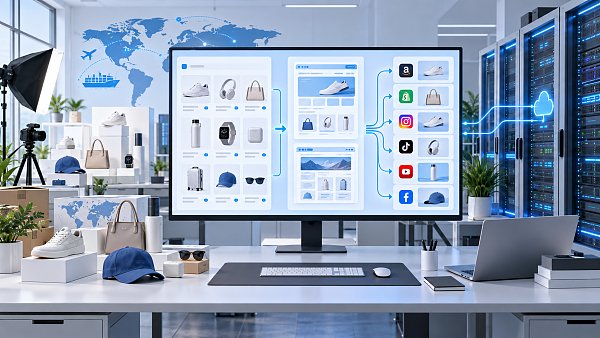
The practice of “automatically translating and publishing directly” requires caution. Page titles, descriptions, and button text can be automatically generated as drafts, but navigation hierarchy, internal links, and regional content must remain logically consistent. If a language site lacks a corresponding category page but links from a product page to a nonexistent address, it will increase troubleshooting and rework later, whether for organic search or advertising. Before publishing, rules can check link status, duplicate titles, missing image alt text, empty fields, and unreplaced default copy, preventing basic errors at the publishing stage.
Content production should distinguish between what can be scaled and what requires judgment
Repetition in cross-border content is not simply about writing a few more articles; it involves rewriting the same selling point into product descriptions, email subject lines, short-video scripts, ad copy, and social media posts. AI can extract reusable information from product data, search terms, historical assets, and page content, then generate drafts of different lengths and formats according to channel constraints. This avoids starting from a blank document every time and reduces the likelihood of inconsistent messaging across channels.
However, not all content should be handed over to automated generation. Where performance claims, delivery lead times, application scope, certification statements, price discounts, or after-sales conditions are involved, content must reference confirmed fields or approved materials. Advertising copy in particular is subject to character limits that force information to be compressed, and the model may omit limiting conditions in order to make the text flow smoothly, causing inconsistencies between the landing page and advertising claims. A more reliable approach is to establish three types of rules for each product category: “permitted expressions,” “required conditions,” and “prohibited inferences,” and then allow AI to expand content within that scope.
- Stable product specifications, packaging information, and page standards are suitable for structured use and batch synchronization.
- Short-term information such as seasonal promotions, inventory fluctuations, and regional delivery should have effective and expiration dates set to prevent outdated assets from continuing to run.
- For high-ticket products or products requiring technical confirmation, the first round of content can be drafted automatically, but core selling points, case descriptions, and form questions still require manual review.
The focus of campaign reuse is “asset tags,” not copying ad groups
Repetitive operations in advertising accounts often occur when new markets, new categories, and new campaigns are launched. Although directly copying an existing ad group is fast, it can also carry over old audiences, old landing pages, old conversion events, and old negative keywords. While this may appear to save setup time in the short term, it becomes difficult to determine later whether a problem comes from the creative, targeting, or page.
A more effective approach is to create searchable tags for assets: product line, language, market, funnel stage, selling-point angle, asset format, corresponding landing page, and applicable date. Based on these tags, an AI marketing engine can identify which assets only require a language change or link replacement and which are no longer suitable for the new market. The same product image may not necessarily be directly reusable, possibly because size preferences or usage scenarios differ, or because the landing page does not provide complete supporting information.
Conversion event definitions should also be unified first. If one channel treats form submissions as the primary conversion while another also counts clicks on a chat button as a primary conversion, the aggregated cost data cannot be directly compared across channels. Before consolidating data, the engine needs to retain the event source, attribution window, deduplication rules, and event value. Otherwise, “more conversions from a certain channel” may simply result from broader measurement criteria rather than better actual customer acquisition performance.
Use anomaly alerts instead of manually reviewing pages one by one
As the number of sites, ads, and content items increases, the most time-consuming task is not publishing, but identifying synchronization gaps. An AI marketing engine can create monitoring tasks around changes: after a product price or inventory status changes, check related ads and landing pages; after a main image is replaced, check whether the social media schedule still references the old image; after form fields are updated, check whether field mappings and lead sources are complete across pages in every language.
Anomaly alerts need to be prioritized. Issues such as missing alt text or minor title duplication can enter a pending queue; broken links, price conflicts, incorrect language redirects, and ads pointing to delisted pages should take priority in blocking publication or pausing related assets. Treating every alert as an urgent task will quickly make the alert system meaningless. Priority should be determined jointly by conversion impact, the number of affected pages, whether transaction information is involved, and whether the content has already been published externally.
Only by tracing reviews back to “versions” can rework in the next round be reduced
Many teams already have data reports but still repeat trial and error because the reports record only results, not the corresponding page versions, asset versions, and rule versions. When click-through rates decline, the cause may be ad creative fatigue, slower page loading, inventory changes, search term shifts, or the loss of key selling points after a page modification. Without version associations, subsequent work can only rely on memory and guesswork, followed by another round of testing.
Every publication should leave traceable information: when a change was made, which field was changed, which pages and assets were affected, whether it was synchronized to the campaign side, and which metrics were observed after launch. AI can connect these records with traffic, conversion, and page behavior data, prioritizing alerts for areas with significant differences before and after a change. The purpose is not to have the system replace judgment, but to narrow the scope of investigation and avoid rechecking all pages, all ads, and all content.
As product information, page modules, asset tags, and data definitions are gradually unified, cross-border e-commerce work will shift from repeated copying to maintaining rules and handling exceptions. The parts that truly require manual input can then be focused on market judgment, content review, and anomaly decisions, rather than being consumed by repetitive transfers between multiple backends.
Related Articles
 How Do AI Marketing Cases Reflect Changes in Content Production?
 AI Content Generation for Export Websites: How to Prevent Errors in Product Specifications and Translation
 How Can AI Drive Website Content Updates as an Engine of Innovation?
Related Products
 Yiyingbao SaaS Intelligent Website Building and Marketing SystemYiyingbao SaaS Intelligent Website Building and Marketing System, AI-powered no-code website building, rapid creation of multilingual B2B international websites in 10 minutes, global server acceleration, AI-powered SEO optimization, helping businesses connect efficiently with global markets. The perfect integration of technology and operation makes building an international trade website remarkably simple
 AI+SEM Intelligent Advertising Marketing SystemAI+SEM drives intelligent ad creation, empowering full-funnel precision advertising marketing. The system automatically generates weekly/monthly reports, AI recommends keywords and target countries, monitors core metrics in real-time with intelligent alerts, and enables one-click high-conversion ad solutions to help quickly acquire customers and improve ROI.
 AI+SEO Dual-Engine System Optimization ServicesYiyingbao’s AI+SEO dual-engine optimization system helps foreign trade enterprises acquire high-quality organic traffic through AI-powered keyword research, content generation, and comprehensive technical optimization, significantly improving search rankings and conversion rates.
 AI+SNS Social Media Marketing SystemYingbao AI+SNS Social Media Marketing System - Precision social capture for the social media era. Supports one-click content synchronization across major platforms like Facebook and LinkedIn. AI intelligently rewrites posts for enhanced relevance. 24/7 AI customer service and user profiling analysis empower businesses to efficiently expand into global markets.
 AI+SEO营销解决方案易营宝AI+SEO营销解决方案,通过AI批量写作、智能生成TDK、精准关键词扩词等功能,全面优化网站SEO效果,提升流量与转化率。助力企业构建高效智能网站新生态。
 AI+SEM Advertising Marketing SolutionsAI+SEM Advertising Marketing Solution leverages AI technology to deeply empower SEM ad campaigns. It automatically generates weekly/monthly reports using AI, presenting account data across multiple dimensions for comprehensive insights into campaign performance and trends. The system precisely recommends keywords and target countries, intelligently generates high-conversion ad copy, and enables one-click activation of efficient campaign plans to help businesses rapidly acquire customers. Simultaneously, it monitors core metrics in real time, intelligently identifies abnormal fluctuations, and issues timely alerts to ensure stable, high-return advertising results.
 Domain Name ServicesEasyWin provides professional domain name services, including intelligent queries, one-stop registration, brand protection, and full lifecycle management, helping businesses build a digital brand image.
 EasyOperate B2C Cross-Border E-Commerce Platform & Independent WebsiteEasyStore B2C Cross-border E-commerce Independent Store is an intelligent website building and cross-border e-commerce integrated solution independently developed by EasyStore Information Technology (Beijing) Co., Ltd. The system is specially designed for small and medium-sized as well as large export enterprises, integrating 'website building, operation, marketing, advertising, and conversion' into one, helping enterprises quickly establish cross-border e-commerce independent stores to achieve brand globalization and global sales growth.
The platform supports multiple languages, multiple currencies, and multi-channel marketing, with built-in AI intelligent translation and SEO optimization systems, suitable for mainstream markets such as Southeast Asia, Europe and America, Latin America, and the Middle East, assisting Chinese manufacturing enterprises in efficiently deploying international e-commerce strategies. SSL证书易营宝提供专业SSL安全证书服务,包括单域名和泛域名证书,确保网站数据传输加密、身份验证和完整性保护,助力企业建立安全可信的在线业务环境。









