









- Which customer acquisition channels will be affected by cross-border marketing trends in 2026?Sep 06, 2026View details
- Which homogenization risks should be considered in an analysis of the AI-powered website building industry?Aug 30, 2026View details
- How Will AI Marketing Trends 2026 Change Advertising Budget AllocationAug 28, 2026View details
- Is the EV SSL certificate market shrinking or upgrading? How should companies assess certificate procurement?Aug 11, 2026View details
- Why the old AMP SEO 2020 practices no longer work and what has changed in current optimization prioritiesAug 02, 2026View details
- How to Choose Topics for an Industry News Section to Attract More Organic Search TrafficJul 29, 2026View details
How to optimize SEO for web crawling? The troubleshooting order from robots.txt to log analysis.
Inadequate SEO optimization and crawling can render even the most complete website content merely "publishable" rather than "discoverable." For businesses reliant on independent websites for customer acquisition, smooth crawling directly impacts indexing efficiency, page exposure, and subsequent conversion rates. Especially in scenarios where website building, SEO optimization, and advertising are coordinated, crawling issues are often not single points of failure but rather a combination of rule configuration, website structure, and server response problems.
The core of technical SEO optimization is not just getting search engines to "come," but also ensuring they efficiently access truly important pages. Without a proper order during troubleshooting, it's easy to get bogged down in piecemeal fixes; a step-by-step check, starting with robots.txt, site structure, status codes, page rendering, and then log analysis, usually makes it easier to find the root cause.
First, check the robots.txt file; don't block the entrance from entering.
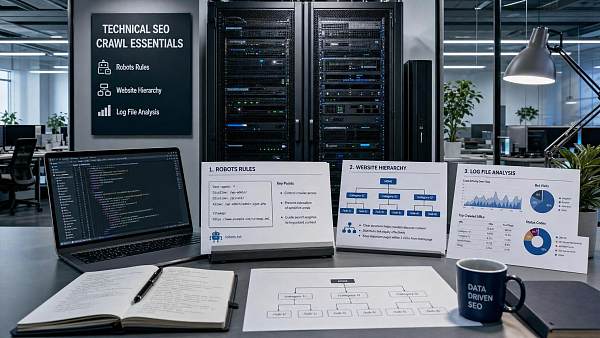
The robots.txt file is the starting point for technical SEO optimization and crawling troubleshooting. It doesn't determine page quality, but it directly affects whether search engines can access directories, parameter pages, image resource pages, and script resource paths. Many sites experience indexing anomalies after launch, and the first thing to check is often leftover testing rules or incorrectly blocked multilingual directories.
Common issues are not complex, such as site-wide disallowing, blocking important directories, incorrect sitemap paths, or intercepting necessary JS and CSS resources for rendering. While the page may appear to load, search engines are actually receiving an incomplete version, which naturally impacts SEO optimization and crawling.
- Confirm whether any test environment rules have been migrated to the production site.
- Check if the multilingual directory, product directory, and blog directory have been mistakenly blocked.
- Verify that the Sitemap address is accessible and consistent with the current URL structure.
- Avoid blocking static resources that the page rendering depends on.
Site structure determines crawl depth and resource allocation
Just because robots.txt doesn't mean that technical SEO optimization will ensure smooth crawling. Search engines determine which pages deserve priority based on the site's structure. If important pages are buried too deep or internal links are disorganized, the crawling budget will be consumed by pagination, page filtering, and duplicate paths.
For marketing websites and cross-border independent websites, the category logic should ideally revolve around business objectives. A clear upstream and downstream relationship needs to be established between product pages, solution pages, case study pages, and content pages. The homepage only serves as the entry point; what truly impacts crawling efficiency are the length of the directory hierarchy, the clarity of anchor text, and the absence of numerous orphaned pages within the site.
Several easily overlooked structural signals
- The crawling frequency drops significantly after clicking too deeply on important pages, usually exceeding three layers.
- The parameter page and filter page can expand indefinitely, easily creating duplicate URLs.
- The lack of breadcrumbs, related recommendations, and thematic aggregations leads to a break in internal communication.
- The lack of standardized correspondence between multiple language versions will lead to confusion in crawling and indexing.
In projects that integrate website and marketing services, addressing structural issues during the website building phase is far less costly than later repairs. Platforms like YiYingBao, which simultaneously cover intelligent website building, SEO optimization, and overseas marketing, offer the value of further transforming a "displayable website" into a "crawlable, indexable, and convertible website," avoiding a situation where technology and marketing are each handled only partially.
Status codes are not a minor issue; they determine whether fetching is wasted.
Once the SEO crawler reaches the execution layer, the most direct signal is the status code. When a search engine accesses a page, if it frequently encounters 3xx excessively long URLs, 4xx invalid addresses, or 5xx server errors, it will reduce access efficiency and may even require a reassessment of the site's stability.
The problem with many projects isn't individual errors, but the scale of errors. For example, after migrating from the old URL, internal links still point to redirected pages; activity pages return blank 200 pages after being taken offline; and there's no clear 410 or 301 error return after a product is deleted. All of these continuously consume technical SEO optimization and crawling resources.
If a site simultaneously handles SEO traffic and advertising landing pages, the stability of status codes becomes even more crucial. Crawl errors not only affect organic indexing but also impact page quality assessments and the performance of the marketing chain.
A page being able to open does not mean that the search engine can understand it correctly.
Another common misconception in technical SEO optimization is assuming that "visible to browsers" is "readable by search engines." In reality, front-end rendering methods, initial page content output, and proper tag settings all affect the parsed results after crawling.
If the core content relies on scripts loaded afterward, the search engine may only see an empty page during its first crawl. Other issues, such as incorrect canonical pointers, mistakenly added noindex, or mismatched hreflang, can prevent effective indexing even if SEO optimizations are performed during the crawl.
This layer requires careful verification.
- Whether the core text, title, and internal links are visible in the first HTML.
- Is the canonical display consistent, or is it incorrectly redirecting to the homepage or other language pages?
- Does `noindex` and `nofollow` appear on pages that shouldn't be restricted?
- Do pagination, tab pages, and search results pages have clear indexing strategies?
This step is especially crucial for multilingual independent websites. When operating in multiple regions such as North America, Europe, and Southeast Asia, if different language versions simply copy the URL path without a standardized mapping relationship, the crawling signals will be scattered, and the pages will be more easily judged as duplicates.
Log analysis is the basis for determining the priority of issues.
The preceding checks are more like static investigations, while log analysis answers another question: what does the search engine actually crawl, how often does it crawl, and where are resources wasted? Only when technical SEO optimization and crawling reach this stage can the judgment truly approach the reality of the business.
Logs reveal the directory distribution accessed by search engines, status code ratios, peak crawling times, repeated access paths, and whether new pages are discovered promptly. Many teams assume that the lack of ranking for important product pages is a content issue, but logs often show that these pages are barely crawled.
More importantly, logs can help distinguish between "theoretical problems" and "real bottlenecks." Some 404 errors may seem numerous, but they all originate from old images; some seemingly harmless parameters may account for a large portion of crawl frequency. Without logs, such judgments are easily misjudged.
Metrics to focus on in the logs
- Do the top ten directories crawled by the search engine meet business priorities?
- Are frequently crawled URLs concentrated on parameter pages, redirect pages, or worthless pages?
- How long is the interval between the launch of a newly published page and its first crawl?
- Are 5xx items concentrated in fixed time periods or using fixed templates?
Put the technical SEO optimization and crawling back into the business process.
SEO optimization and crawling are not isolated technical actions; they are related to website architecture, content production, advertising, and overseas market strategy. For a website targeting global customer acquisition, a poor crawling process will negatively impact content creation and advertising coordination.
In real-world projects, websites with the fewest issues typically share several common characteristics: their website building systems support standardized URLs and template controls; their content publishing processes have index verification; their marketing landing pages don't arbitrarily copy paths; and their technical and operational teams use the same monitoring standards. In this way, technical SEO optimization and crawling are no longer reactive measures, but rather incorporated into quality standards before launch.
The reason why platforms like YiYingBao are suitable for overseas independent websites lies here. It doesn't just provide front-end page building; it combines intelligent website building, SEO/GEO optimization, advertising and marketing systems with multilingual business scenarios, creating a continuous flow from crawling and indexing to exposure and conversion.
When conducting the investigation, you can first create a priority list.
If you need to quickly determine the current SEO crawling status of a site, a more practical approach is to sort by the scope of impact, rather than by the ease of using the tools. First, check if it will be blocked; then, see if it can be found; next, confirm if it returns consistently; and finally, use logs to verify if resources are being allocated to key pages.
- First layer: Are robots, Sitemap, and indexing instructions correct?
- The second layer: Whether the directory structure, internal links, and click depth are reasonable.
- The third layer: status codes, redirects, and whether the server stability is up to standard.
- The fourth layer: whether the rendering, standardization of tags, and multilingual mapping are accurate.
- Fifth layer: Does the log prove that the crawled resources flowed to important pages?
What's truly valuable isn't the number of problems discovered at once, but rather the ability to establish a continuous monitoring mechanism. For projects evaluating website building systems, SEO services, or overseas marketing solutions, first clarifying the criteria for judging technical SEO optimization and crawling, then comparing the platform's capabilities, implementation processes, and maintenance costs is often more reliable than simply looking at traffic promises.
Related Articles

Related Products
 Yiyingbao SaaS Intelligent Website Building and Marketing SystemYiyingbao SaaS Intelligent Website Building and Marketing System, AI-powered no-code website building, rapid creation of multilingual B2B international websites in 10 minutes, global server acceleration, AI-powered SEO optimization, helping businesses connect efficiently with global markets. The perfect integration of technology and operation makes building an international trade website remarkably simple
 AI+SEM Intelligent Advertising Marketing SystemAI+SEM drives intelligent ad creation, empowering full-funnel precision advertising marketing. The system automatically generates weekly/monthly reports, AI recommends keywords and target countries, monitors core metrics in real-time with intelligent alerts, and enables one-click high-conversion ad solutions to help quickly acquire customers and improve ROI.
 AI+SEO Dual-Engine System Optimization ServicesYiyingbao’s AI+SEO dual-engine optimization system helps foreign trade enterprises acquire high-quality organic traffic through AI-powered keyword research, content generation, and comprehensive technical optimization, significantly improving search rankings and conversion rates.
 AI+SNS Social Media Marketing SystemYingbao AI+SNS Social Media Marketing System - Precision social capture for the social media era. Supports one-click content synchronization across major platforms like Facebook and LinkedIn. AI intelligently rewrites posts for enhanced relevance. 24/7 AI customer service and user profiling analysis empower businesses to efficiently expand into global markets.
 AI+SEO营销解决方案易营宝AI+SEO营销解决方案,通过AI批量写作、智能生成TDK、精准关键词扩词等功能,全面优化网站SEO效果,提升流量与转化率。助力企业构建高效智能网站新生态。
 AI+SEM Advertising Marketing SolutionsAI+SEM Advertising Marketing Solution leverages AI technology to deeply empower SEM ad campaigns. It automatically generates weekly/monthly reports using AI, presenting account data across multiple dimensions for comprehensive insights into campaign performance and trends. The system precisely recommends keywords and target countries, intelligently generates high-conversion ad copy, and enables one-click activation of efficient campaign plans to help businesses rapidly acquire customers. Simultaneously, it monitors core metrics in real time, intelligently identifies abnormal fluctuations, and issues timely alerts to ensure stable, high-return advertising results.
 Domain Name ServicesEasyWin provides professional domain name services, including intelligent queries, one-stop registration, brand protection, and full lifecycle management, helping businesses build a digital brand image.
 EasyOperate B2C Cross-Border E-Commerce Platform & Independent WebsiteEasyStore B2C Cross-border E-commerce Independent Store is an intelligent website building and cross-border e-commerce integrated solution independently developed by EasyStore Information Technology (Beijing) Co., Ltd. The system is specially designed for small and medium-sized as well as large export enterprises, integrating 'website building, operation, marketing, advertising, and conversion' into one, helping enterprises quickly establish cross-border e-commerce independent stores to achieve brand globalization and global sales growth.
The platform supports multiple languages, multiple currencies, and multi-channel marketing, with built-in AI intelligent translation and SEO optimization systems, suitable for mainstream markets such as Southeast Asia, Europe and America, Latin America, and the Middle East, assisting Chinese manufacturing enterprises in efficiently deploying international e-commerce strategies. SSL证书易营宝提供专业SSL安全证书服务,包括单域名和泛域名证书,确保网站数据传输加密、身份验证和完整性保护,助力企业建立安全可信的在线业务环境。









