- CBP Finalizes Electronic Rail Export Manifest Rule, Effective October 26, 2026Oct 26, 2026View details
- Amazon’s 2026 peak season surcharge takes effect on October 25Oct 26, 2026View details
- AI Is Eating SaaS: Three Real-World Cases in One AfternoonOct 25, 2026View details
- Exiger CEO: The SaaS Apocalypse Is Real, but It Means Something DifferentOct 25, 2026View details
- Hengqin Cooperation Zone Shares Cross-Border E-Commerce Developments, Focusing on Macao-Hengqin Collaboration and International MarketsOct 24, 2026View details
- A Shenyang study highlights the development of the “cross-border e-commerce + industrial cluster” modelOct 24, 2026View details
How Can You Use Time-Tracking Data to Quantify the Efficiency of Multilingual Marketing Automation?
To quantify the efficiency of multilingual marketing automation, first compare the labor hours required per accepted deliverable unit for tasks of the same scope and quality, then review the rework rate and publishing cycle. Faster translation generation only shows that one stage has sped up. If proofreading, page adaptation, and publishing fixes increase, total labor hours may still rise.
A set of multilingual landing pages can serve as the evaluation sample, covering content processing, page configuration, search optimization, form validation, and launch acceptance. First establish a baseline for the manual workflow, then record the actual effort required by the automated workflow, ensuring both sets of data cover the same deliverables.
Standardize the task definition first to make labor hours comparable
“Completing a page” is too vague. A short advertising page cannot be averaged directly with a product page containing technical specifications, downloadable materials, and an inquiry form. We recommend using “source page × target language × delivery version” as the task unit and recording content length, page type, language pair, and degree of reuse.
The initial setup of a terminology database, page templates, and publishing rules requires effort that does not need to be repeated for subsequent tasks. Record this effort separately and allocate it across the agreed evaluation batch. Comparing only the first run will underestimate ongoing benefits; ignoring the initial investment entirely will exaggerate short-term results.
Historical records for similar tasks are the preferred source for the baseline. If historical labor-hour data is unavailable, use a small batch of tasks to establish a manual benchmark, keeping the source content, acceptance criteria, and delivery scope consistent. Do not directly compare a manual team familiar with the business against an automated workflow that has just been configured, and do not treat historical estimates as precise measurements.
Labor-hour records must include work performed after generation
Start timing when task preparation begins and stop when acceptance is passed. When multiple people work on a task simultaneously, add together their individual labor hours. Record approval waits, machine run time, and time spent in interface queues separately as elapsed time; do not count them as labor input. Otherwise, unattended time during automated batch processing will skew the efficiency metric downward.
Flag rework separately within the total effort above; do not add it again when calculating totals. Also distinguish requirement changes from defect rework: redo work caused by last-minute source-copy changes and edits caused by mistranslated terminology reflect different issues.
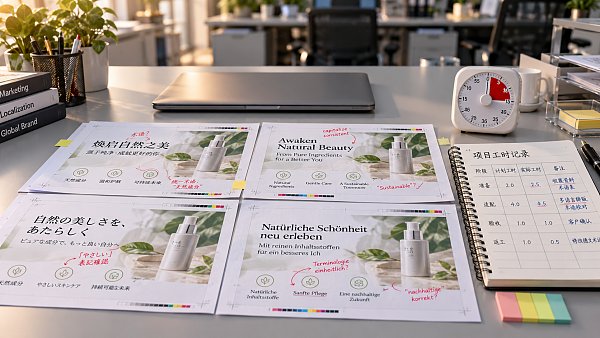
Use four metrics to determine whether the benefits are real
Labor hours per accepted output unit = total labor hours within the evaluation scope ÷ number of accepted deliverable units.The numerator includes failed tasks, rework, and allocated setup effort, so that only counting successful tasks is avoided. Tasks that have not yet passed acceptance must be marked as work in progress and cannot be counted as output in advance. If the batch is not yet complete, the result can only be treated as interim data.
Labor-hour savings rate = (baseline labor hours per unit − labor hours per unit after automation) ÷ baseline labor hours per unit × 100%.This percentage is meaningful only when task difficulty and quality thresholds are consistent. If simpler pages make up a larger share of later work, calculate the rate separately by page type and language, then aggregate using a fixed task mix.
Rework labor-hour ratio = defect rework hours ÷ total labor hours × 100%.This reveals whether time saved during generation is being consumed by review and fixes, but it should also be assessed alongside rework hours per output unit. When total labor hours fall significantly, the ratio may rise even if the absolute rework effort has not increased.
First-pass acceptance rate = number of deliverable units accepted on first submission ÷ number of deliverable units submitted for the first time × 100%.Acceptance criteria must be fixed and should cover, at a minimum, terminology accuracy, content completeness, page display, language switching, and conversion functionality. A higher pass rate achieved by lowering review requirements cannot be considered an efficiency improvement.
Apply quality thresholds to the details of multilingual websites
An accurate literal translation does not mean a page is ready to publish. Whether the title and description match the page topic, language-version links are correct, button text is truncated due to changes in text length, and inquiry forms pass along language and source information can all affect delivery quality. Languages that use right-to-left layout also require separate validation of layout and interaction order.
Acceptance criteria can distinguish between issues that block publication and those that can be scheduled for later correction. Errors in prices or specifications, nonfunctional forms, and missing key content should block publication according to pre-agreed rules; wording refinements should be handled according to content requirements. Both workflows must use the same criteria, or the definition of “accepted output” will shift.
The post-launch observation window should also be consistent. If the manual workflow includes post-launch fixes in its figures, while the automated workflow stops tracking time on the day of publication, the latter will appear to require fewer labor hours. When missing translations, incorrect redirects, or form issues are discovered, associate the effort required to fix them with the original task batch.
Use data differences to guide the next round of adjustments
If generation hours decrease while review hours increase, first check terminology constraints and ambiguity in the source copy. If page configuration time is concentrated in a few languages, check whether the templates accommodate text length and writing direction. If effort per page has fallen but overall publishing is still slow, review approval waits and publishing dependencies rather than continuing to optimize the generation stage, which has already sped up.
Evaluation records should also retain workflow versions. After changes to the terminology database, templates, or review rules, mark the batch in which the changes take effect, then track labor hours per unit and first-pass acceptance rates for comparable tasks. Only when quality thresholds remain stable, task mixes are comparable, and ongoing configuration maintenance is included can a reduction in labor hours support a decision to expand automation.
Related Articles
 How Can You Use Time-Tracking Data to Quantify the Efficiency of Multilingual Marketing Automation?
 How can you use data from a SaaS marketing platform to identify sources of high-quality leads?
 How Can Cross-Border E-Commerce Businesses Avoid Exaggerated Claims in AI-Generated Product Descriptions?
Related Products
 Yiyingbao SaaS Intelligent Website Building and Marketing SystemYiyingbao SaaS Intelligent Website Building and Marketing System, AI-powered no-code website building, rapid creation of multilingual B2B international websites in 10 minutes, global server acceleration, AI-powered SEO optimization, helping businesses connect efficiently with global markets. The perfect integration of technology and operation makes building an international trade website remarkably simple
 AI+SEM Intelligent Advertising Marketing SystemAI+SEM drives intelligent ad creation, empowering full-funnel precision advertising marketing. The system automatically generates weekly/monthly reports, AI recommends keywords and target countries, monitors core metrics in real-time with intelligent alerts, and enables one-click high-conversion ad solutions to help quickly acquire customers and improve ROI.
 AI+SEO Dual-Engine System Optimization ServicesYiyingbao’s AI+SEO dual-engine optimization system helps foreign trade enterprises acquire high-quality organic traffic through AI-powered keyword research, content generation, and comprehensive technical optimization, significantly improving search rankings and conversion rates.
 AI+SNS Social Media Marketing SystemYingbao AI+SNS Social Media Marketing System - Precision social capture for the social media era. Supports one-click content synchronization across major platforms like Facebook and LinkedIn. AI intelligently rewrites posts for enhanced relevance. 24/7 AI customer service and user profiling analysis empower businesses to efficiently expand into global markets.
 AI+SEO营销解决方案易营宝AI+SEO营销解决方案,通过AI批量写作、智能生成TDK、精准关键词扩词等功能,全面优化网站SEO效果,提升流量与转化率。助力企业构建高效智能网站新生态。
 AI+SEM Advertising Marketing SolutionsAI+SEM Advertising Marketing Solution leverages AI technology to deeply empower SEM ad campaigns. It automatically generates weekly/monthly reports using AI, presenting account data across multiple dimensions for comprehensive insights into campaign performance and trends. The system precisely recommends keywords and target countries, intelligently generates high-conversion ad copy, and enables one-click activation of efficient campaign plans to help businesses rapidly acquire customers. Simultaneously, it monitors core metrics in real time, intelligently identifies abnormal fluctuations, and issues timely alerts to ensure stable, high-return advertising results.
 Domain Name ServicesEasyWin provides professional domain name services, including intelligent queries, one-stop registration, brand protection, and full lifecycle management, helping businesses build a digital brand image.
 EasyOperate B2C Cross-Border E-Commerce Platform & Independent WebsiteEasyStore B2C Cross-border E-commerce Independent Store is an intelligent website building and cross-border e-commerce integrated solution independently developed by EasyStore Information Technology (Beijing) Co., Ltd. The system is specially designed for small and medium-sized as well as large export enterprises, integrating 'website building, operation, marketing, advertising, and conversion' into one, helping enterprises quickly establish cross-border e-commerce independent stores to achieve brand globalization and global sales growth.
The platform supports multiple languages, multiple currencies, and multi-channel marketing, with built-in AI intelligent translation and SEO optimization systems, suitable for mainstream markets such as Southeast Asia, Europe and America, Latin America, and the Middle East, assisting Chinese manufacturing enterprises in efficiently deploying international e-commerce strategies. SSL证书易营宝提供专业SSL安全证书服务,包括单域名和泛域名证书,确保网站数据传输加密、身份验证和完整性保护,助力企业建立安全可信的在线业务环境。