The website is live, and the pages can also be opened normally, but Google still doesn’t index them?
This is not a problem that can be solved by simply “submitting the URL.”
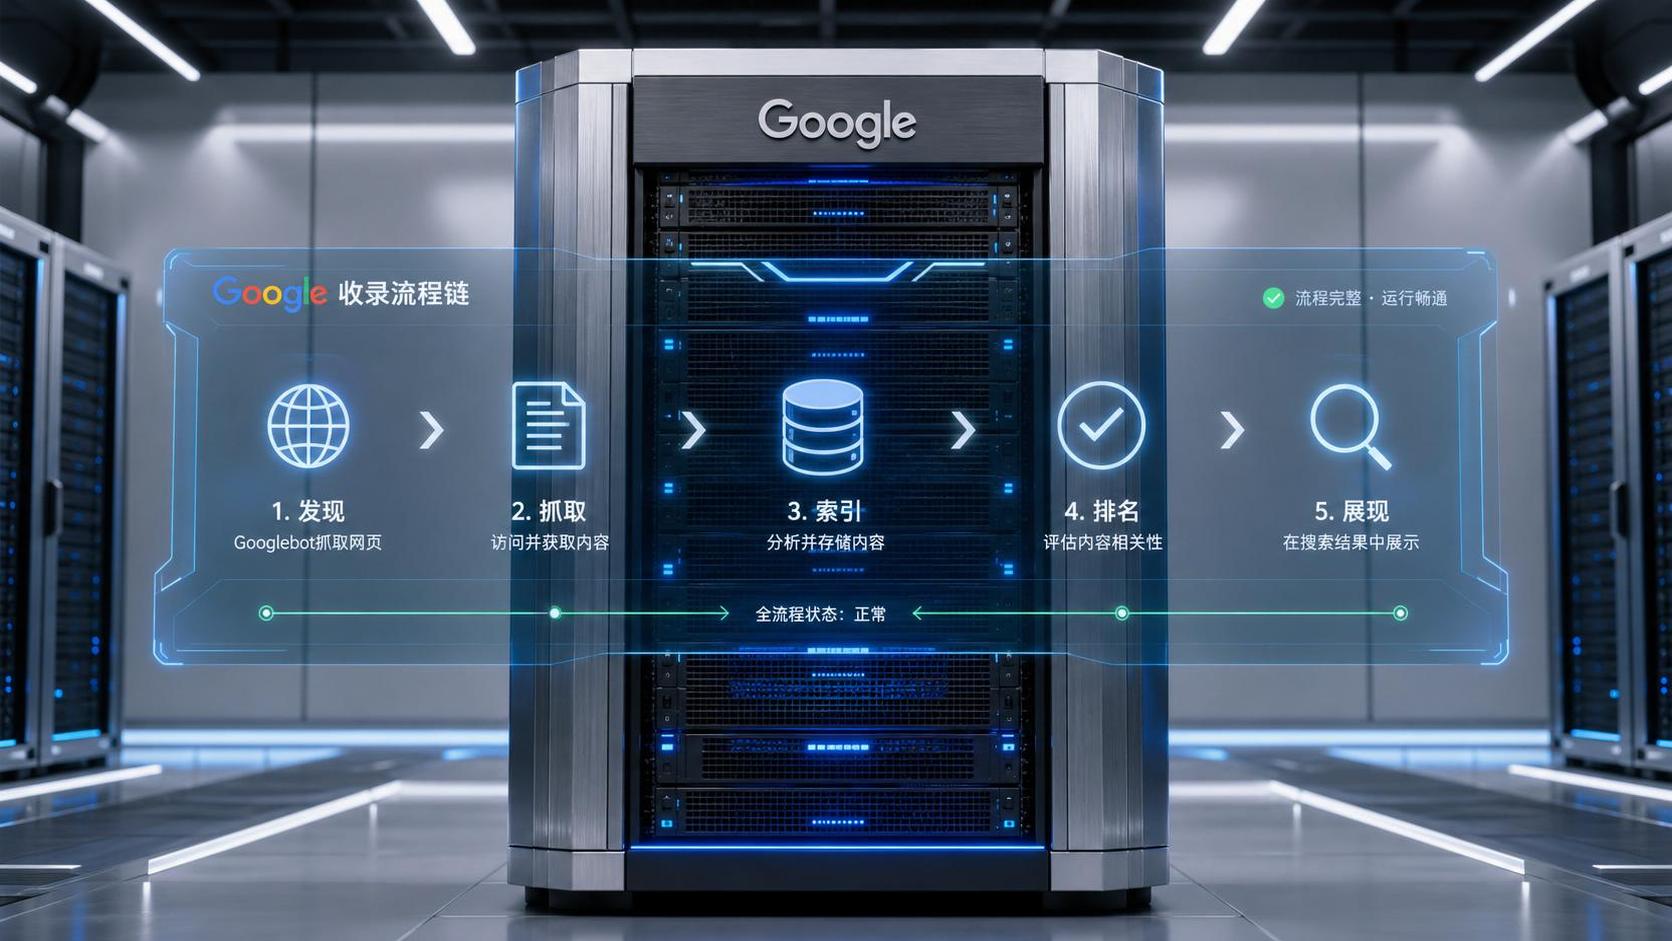
Google indexing usually goes through several stages: discovering the URL, crawling the page, understanding the content, and determining whether it is worth indexing. If any one of these steps has a problem, the page may show up as “not discovered,” “crawled but not indexed,” “duplicate webpage,” “excluded by noindex,” and so on.
This topic will systematically help you troubleshoot Google indexing issues from 7 key modules.
Module 1: First determine which stage the problem occurs in
For many websites that are not indexed, the issue is not that Google cannot find the page at all, but that the page gets stuck during crawling, indexing, or the quality evaluation stage.
You need to first confirm:
Has Google discovered the URL?
Can Googlebot access the page?
Is the page blocked by robots.txt or noindex?
Does the canonical point to the wrong page?
Is the page content sufficiently unique and valuable?
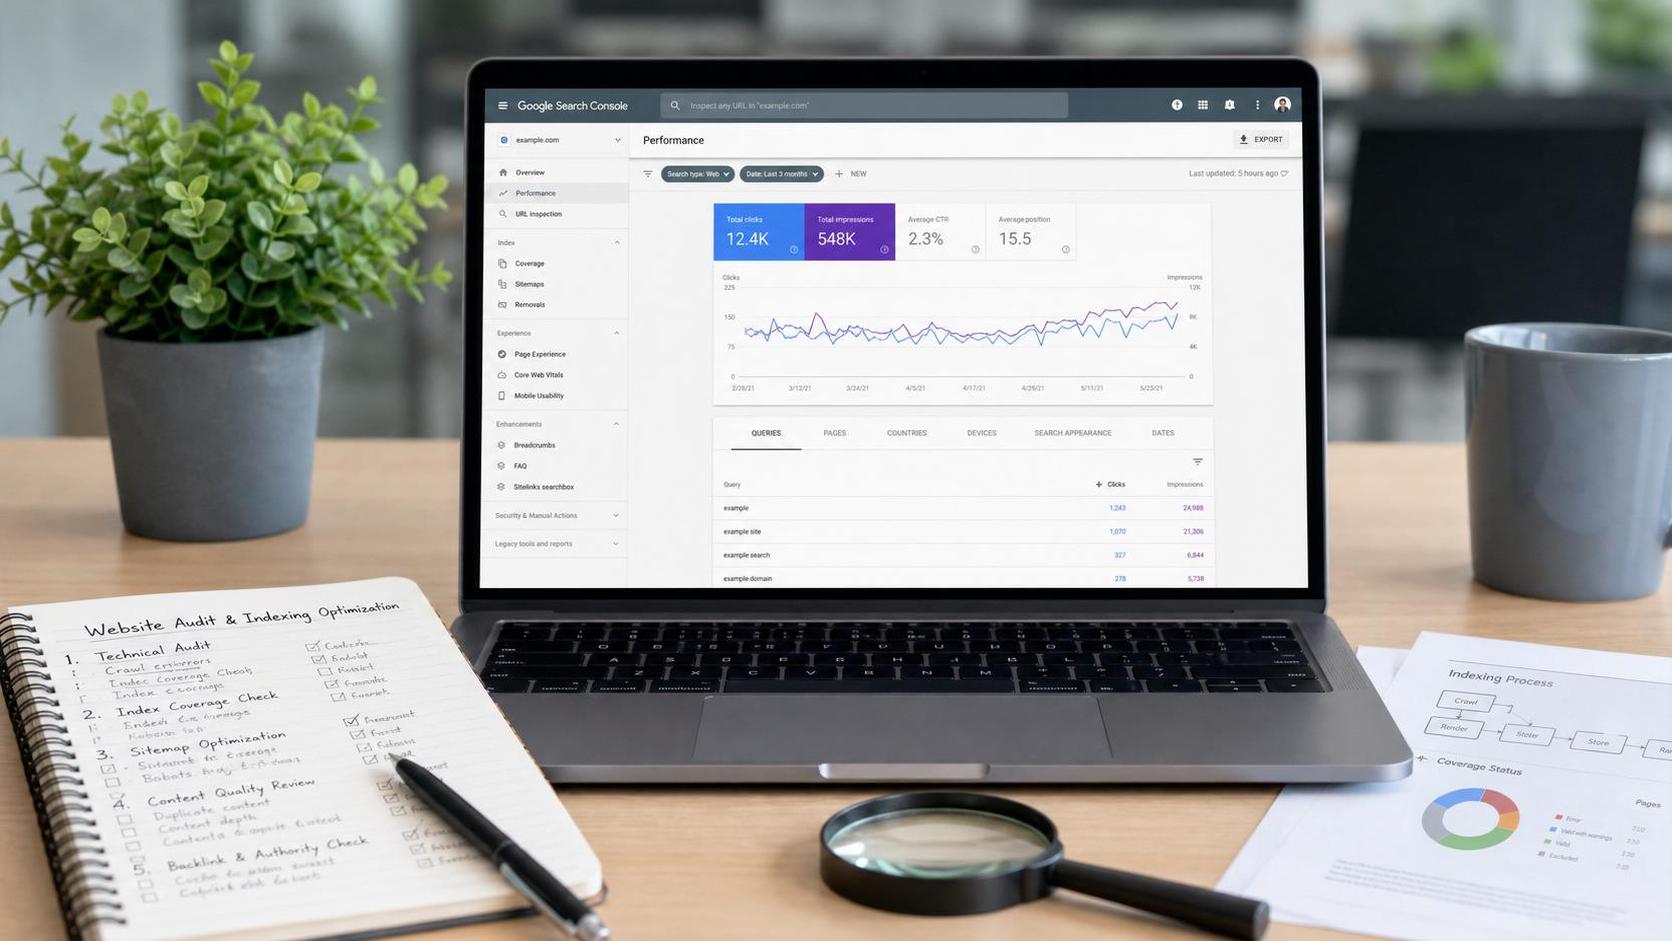
In GSC, does it show “not discovered” or “crawled but not indexed”?
Recommended link page:
[Why is the website not indexed by Google? Common causes and troubleshooting methods]